Agent Evaluation Framework Selection for GitHub-Hosted Pipelines
Trajectory-level evaluation catches agent failures that outcome metrics hide before merge.
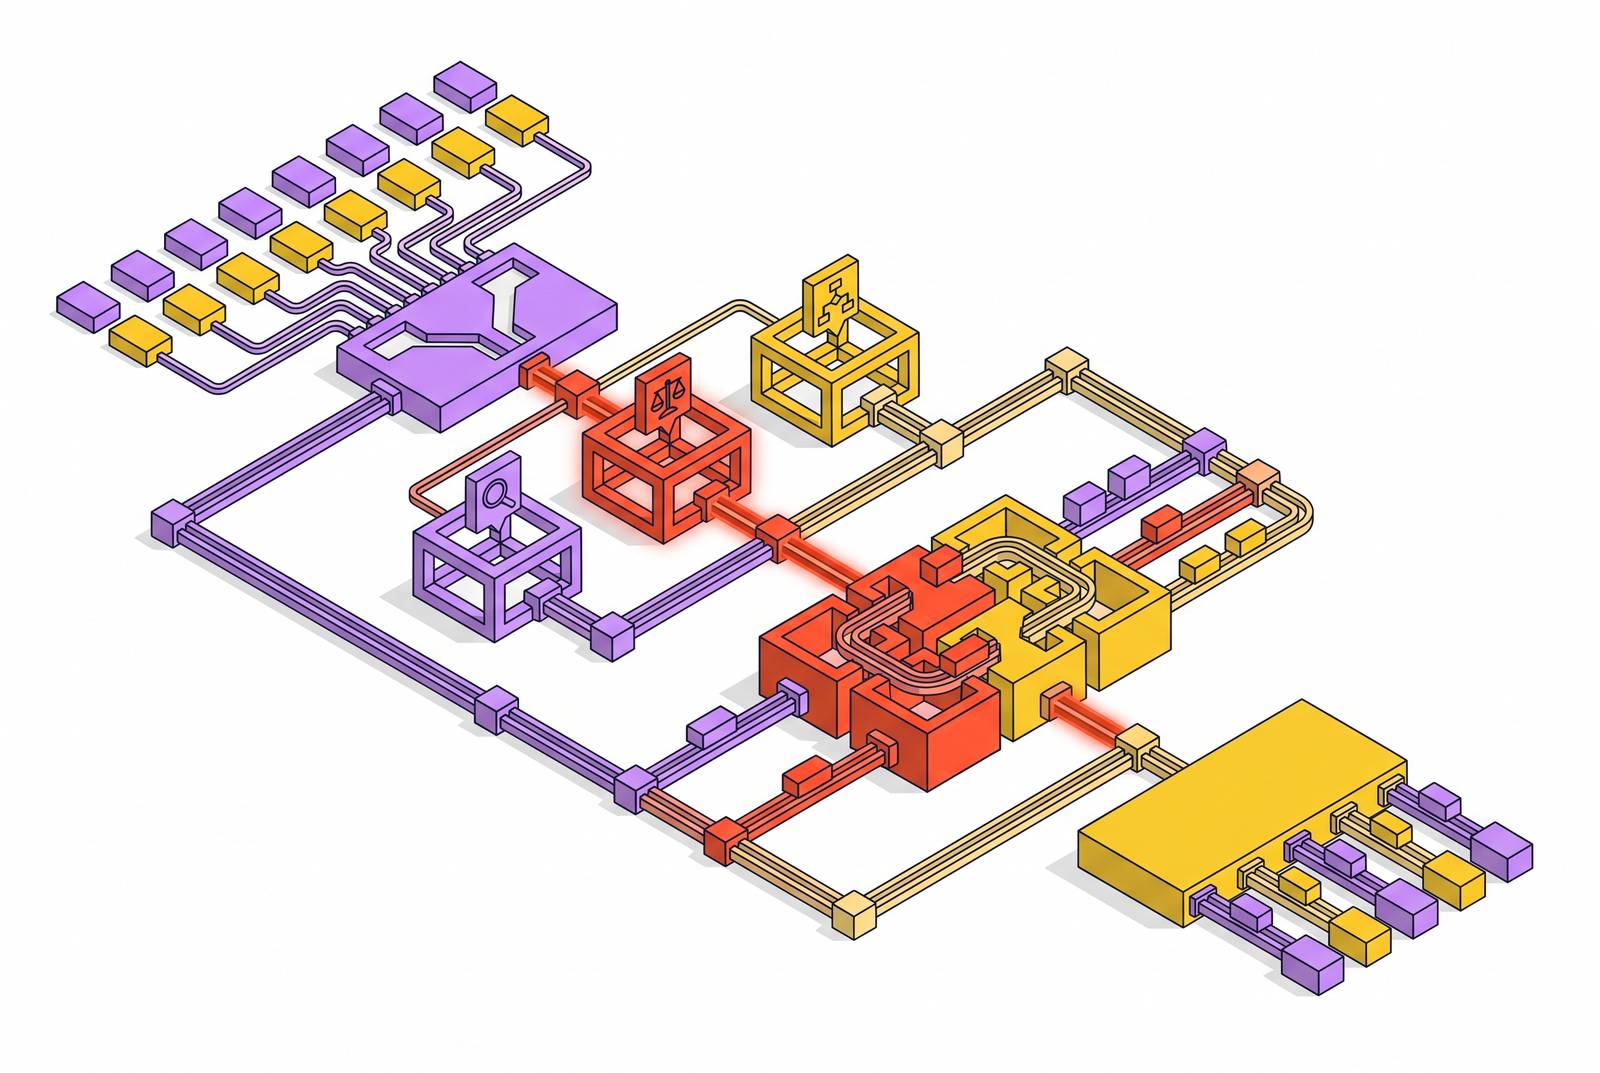
The pull request was never designed to be a quality gate for machine-authored code. It became one in 2026, when the standard agentic workflow settled into a loop: plan in the IDE, execute autonomously, verify in CI, checkpoint through a PR. The merge boundary now enforces quality for work no human wrote line by line. Choosing an evaluation framework for that boundary is therefore not a tooling preference. It is a CI architecture decision.
Why agent-generated PRs create a new kind of merge problem
The prevailing agentic coding workflow requires CI and PR review before anything merges. An agent edits files, runs tests, and self-corrects until CI turns green, then it opens a PR. The human sits on the loop at review and merge, not at every step in between. That arrangement works acceptably when agents produce a handful of PRs per day. It breaks down when they produce dozens or hundreds.
At high volume, the merge queue itself becomes the bottleneck. Bisection behavior determines how fast a bad PR gets ejected before it blocks the rest of the batch. If a queue cannot isolate one failing agent PR, it stalls every other PR waiting behind it. The teams that remain stable are the ones pairing agent output with tighter automated checks at merge time.
This structural shift changes what the evaluation problem is. A human reviewer once supplied judgment that machines could not replicate. Now the reviewer is a queue, and the queue needs a signal it can act on. That signal must arrive before merge, in a form the queue can consume. Framework selection becomes the question of which signal can actually gate a pipeline.
Why "did the task succeed?" is the wrong gate for agent PRs
Task success is a lagging indicator that compresses meaningfully different failure modes into a single pass/fail signal. Four distinct failure classes sit inside that binary: the wrong tool chosen for the job, the right tool invoked with wrong arguments, a correct tool call that produces the wrong side effect, and a correct output reached through unnecessary looping. Each class implies a different fix. A binary success metric masks all four.
The problem runs deeper than taxonomy. An agent that leaks a secret into logs, retries six times with near-identical prompts, or takes far longer than the product SLO can all register as task complete. Nothing in the final answer reveals the leak, the retries, or the latency. At the merge boundary specifically, that omission is fatal. A pass/fail outcome score cannot tell the queue whether a PR should be ejected because the agent looped, over-called tools, or violated a policy. It can only say the final diff looked acceptable.
The standard objection is that outcome metrics are simpler to compute and easier to explain to stakeholders. The answer is that simplicity at the metric layer creates complexity at the incident layer. Teams pay for the missing signal either way. The only choice is when.
The three evaluation models and what each one can actually gate
Trajectory-level, step-level, and outcome-based evaluation are not interchangeable. They answer different questions, and only some of those questions are answerable inside a CI pipeline that must produce a pass/fail signal before merge. Outcome-based evaluation scores the final answer or diff. It is the easiest to compute and integrates with any CI runner. It cannot surface intermediate failures. It is adequate only when the agent's action space is narrow and its side effects are reversible. For an agent that writes a README update, that may be enough. For an agent that mutates infrastructure or rewrites database schemas, it is not.
Step-level evaluation scores each tool call, argument, and model invocation on its own. It catches wrong-tool selection, schema invalidity, and argument errors before they compound into something the final answer hides. Step-level evaluation adds latency per step but produces locatable failure signals, which matters when a queue needs to know what to eject and why.
Trajectory-level evaluation scores the full execution path. It assesses tool selection, plan quality, logical consistency, execution efficiency, and plan adherence across the entire reasoning loop, not just the terminal state. This is the most complete signal, but it requires a framework that can parse and score multi-step traces rather than final outputs alone.
Two runs of the same task can take completely different paths and both be correct, or both be wrong for different reasons. Trajectory scoring has to handle this non-determinism by evaluating distributions, not fixed answers. The central argument for trajectory evaluation is compounding failure: a bad result at step three can silently corrupt steps four through ten, so the final answer hides where the damage started. A 2026 analysis of production agent traces found that DAG-based dependency modeling improved failure detection recall by 22 percentage points over flat step-level evaluation. That is the difference between a queue that catches a poisoned trajectory and one that lets it merge.
The CI gating constraint applies to all three models. The evaluation must produce a binary or threshold signal that the merge queue can act on. A trajectory scorer that returns rich structured output is only useful at the merge gate if the pipeline converts that output into a clear block or pass decision. Safety belongs in the same scorecard as reliability. Policy violations, prompt injection susceptibility, and data-exfiltration attempts are trajectory-level signals, not post-merge observability problems.
How the leading frameworks map onto GitHub-hosted CI
The frameworks worth evaluating differ not just in metric coverage but in how naturally they produce a CI-actionable signal. That integration characteristic is the deciding factor for GitHub-hosted pipelines. MLflow brings TruLens-integrated Agent GPA scorers, covering goal, plan, and action evaluation patterns. The judge alignment work sits on research-backed algorithms, GEPA, SIMBA, and MemAlign, which optimize judge prompts against human labels and reduce the gap between automated scores and what reviewers actually care about. MLflow also supports online monitoring, dataset management, multi-turn evaluation, and conversation simulation, making it usable both as a pre-merge gate and as a production signal source. The tradeoff is breadth: it positions itself for teams that need the full evaluation-to-improvement pipeline in one tool, and that breadth adds configuration overhead for teams that only need CI gating.
DeepEval is built for pytest-style CI/CD testing. Its agent-native workflow applies metrics directly to agent traces and plugs into OpenAI Agents, LangChain, CrewAI, and other frameworks. Visualization requires Confident AI, which has a free tier with advanced features on paid plans, so teams running entirely on open-source tooling will need to export results elsewhere. The natural fit is a mature, batteries-included framework with a test-driven workflow already familiar to engineers.
Arize Phoenix extends existing ML observability into LLM evaluation, with particular strength in RAG and trace-based agent evaluation. It is source-available under the ELv2 license, which is not an approved open-source license because it forbids offering the software as a managed service to third parties. Native online monitoring and versioned datasets make it a credible choice for teams that need evaluation to span pre-merge and post-deploy.
Ragas is RAG-focused with some agent metrics, but limited on multi-turn simulation and conversation-level evaluation. It integrates into MLflow as a pluggable scorer, so Ragas metrics work as plugins inside an MLflow-centered pipeline rather than standing alone. The right fit is narrow: agent PRs that primarily involve retrieval-augmented generation steps, where retrieval quality and grounding are the core gating criteria.
LangSmith supports multi-turn evaluation, human feedback collection, and online monitoring. The platform is proprietary, though the client SDKs are MIT-licensed. Judge alignment is manual tuning via UI rather than automated, so teams that need automated calibration against human labels will find MLflow's approach more scalable.
Agentevals and openevals come from LangChain as small, MIT-licensed, unopinionated tools. Agentevals focuses squarely on trajectory and tool-call matching, either against an expected trajectory or with an LLM-as-judge. It drops easily into an existing test suite and is best used when trajectory and tool-call matching is the specific gap, paired with openevals for general LLM application evals.
Strands Evals, from AWS, is the newest and smallest of the established options and the most opinionated about the full agent-eval loop. It builds on three concepts: a Case, containing input, expected output, and expected tool trajectory. An Experiment, bundling cases with evaluators. And an Evaluator, deterministic or LLM-based. It works with recorded trajectories and offline test cases. Reading OpenTelemetry traces from production runs falls to AgentCore Evaluations, the companion managed AWS service.
Promptfoo is command-line-driven with declarative config, so it slots into CI/CD without requiring Python. Its red-team module scans for prompt injection, jailbreaks, PII leaks, and tool misuse, which makes correctness and security the same checklist. OpenAI announced an agreement to acquire Promptfoo in March 2026, and it remains open source under the MIT license. The best fit is when security red-teaming and correctness evaluation need to run in the same CI step.
The offline-versus-production gap that no framework fully closes at the merge boundary
Every framework covered above is primarily an offline evaluator. That means it is structurally blind to a class of agent failure that only appears in live production state. Teams that treat a green pre-merge eval as sufficient will eventually discover this gap in production, and the discovery will be expensive.
Offline evaluation runs against a fixed test set in a synthetic environment. It cannot reproduce permissions errors, idempotency violations, or memory drift across sessions, all of which depend on live state. The synthetic environment itself removes the very conditions that trigger certain failure classes. A clean offline pass can breed false confidence precisely because the environment never presented the agent with the difficulty that caused the failure in the first place.
The strongest version of this objection is familiar: most agent evaluation stops at a held-out benchmark and a final-answer pass/fail, missing trajectory quality, tool-call correctness, looping, and recovery. Those are precisely the signals pre-merge gating needs most. The answer is not to abandon offline evaluation. It is to close the production-to-test feedback loop. The cycle from finding a problem in production to verifying the fix in staging should be short.
Production signals, meaning exceptions, deploy failures, error rates, and latency, should feed directly into agent evaluation datasets rather than sitting in observability dashboards. That structural shift is what makes offline evals increasingly accurate over time. Framework selection remains necessary. It is not sufficient by itself.
Agent-native merge gates: when the agent evaluating the PR is not the agent that wrote it
A distinct pattern is emerging at the merge boundary, one that uses agents on both sides of the gate. Active projects on GitHub show merge queues whose author is a language model. These queues run AI coding agents in isolated git worktrees and merge only what passes build and tests. The fail-closed continuous-delivery pattern takes this further: a branch merges only when an out-of-band AI review persona and an AI test persona have each recorded a pass verdict in a dispatch ledger, executed by a scheduler outside the code-writing agent's scope.
This is a different problem from framework selection. But the enforcement mechanism is now an agent-operated merge gate rather than a CI job that calls a scoring library. You can assemble the evaluation model from the frameworks above and the merge gate logic, whether agent-operated or CI-native, as separate components. No monolithic platform needs to do both.
An agentic merge queue that handles CI failures and queue management, with humans intervening only on meaningful decisions, is the natural infrastructure layer for this pattern. The evaluation framework feeds the signal. The queue acts on it. If you keep those roles distinct, each side can evolve without dragging the other along.
How to match your evaluation model to your pipeline's merge architecture
The right framework is determined by three pipeline characteristics that must be resolved before any tool is selected: the evaluation depth the merge gate requires, the CI signal latency the queue can tolerate, and whether the merge gate is human-operated, CI-native, or agent-operated. If the gate is a standard GitHub Actions required status check, the evaluation framework must produce a pass/fail exit code that a CI job can return. Trajectory-level frameworks such as MLflow, DeepEval, and agentevals are compatible when configured to threshold on a score. Outcome-only frameworks are adequate only for narrow, low-side-effect agent tasks.
If the gate is a speculative merge queue grouping multiple agent PRs, bisection behavior becomes the critical path. The queue must eject a single failing agent PR without blocking the batch. That means the signal is per-PR, not per-batch, and the framework runs inside the per-PR CI job rather than across the group. If the gate is agent-operated, the evaluation framework becomes a signal source for the gating agent, not the gating mechanism itself. Trajectory and step-level signals are more useful than outcome-only scores because the gating agent needs to reason about why a PR failed, not just that it did.
Latency is a first-class constraint. Step-level evaluation adds latency per tool call, so if your CI time budget is tight, you may need to run trajectory evaluation asynchronously and gate on cached results. The code storage architecture faces its own pressure at high agent-generated PR volume. The git storage layer must handle ephemeral CI/CD infrastructure without buckling. Teams that treat git storage as a combination of immutable cloud logs and high-speed local caches resolve the conflict between distributed design and centralized scale that high-volume agent pipelines create.
The composable path follows from all of this. Assemble the evaluation model, meaning the trajectory scorer, the CI integration, meaning a pytest-style runner or a GitHub Actions step, and the merge gate logic, whether a GitHub native merge queue or an agent-operated gate, from best-of-breed components. The merge boundary now carries the full weight of agent-authored code. It deserves infrastructure built for that weight, assembled from parts that each do one job well.