AI Agent Generation of Gherkin Specifications
Agents now draft Gherkin specs to close the verification gap in code generation pipelines.
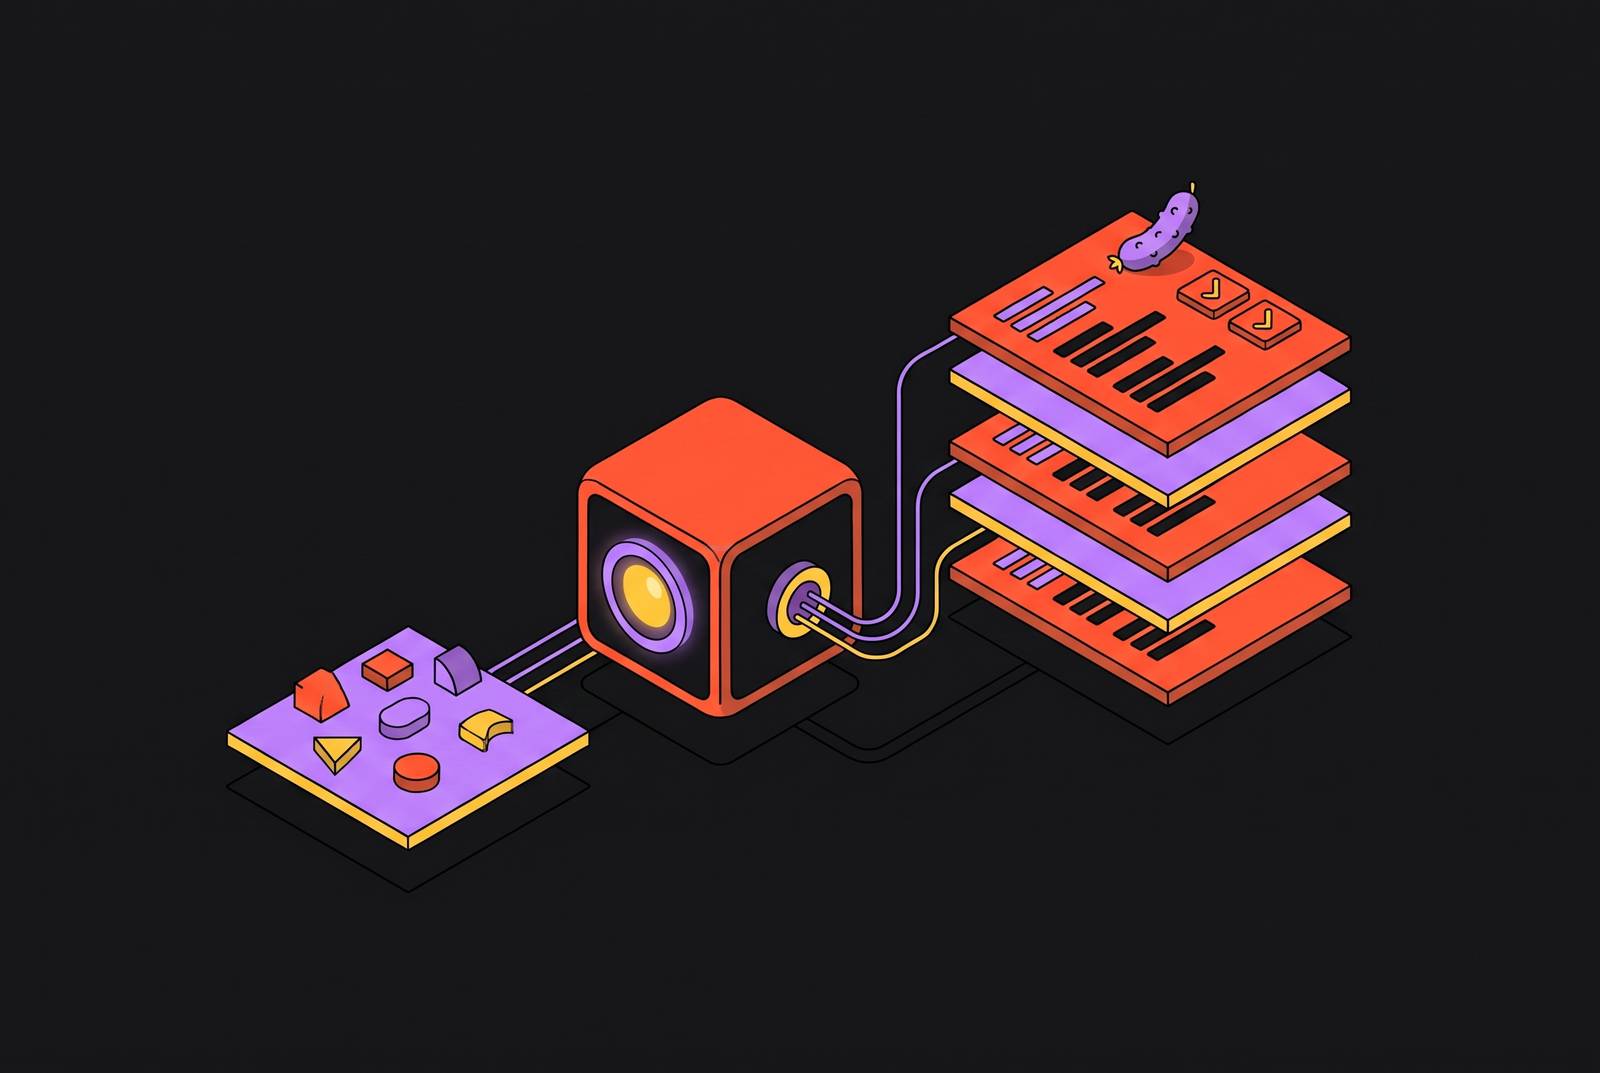
AI agent generation of Gherkin specifications addresses the weakest part of agentic coding pipelines, the translation of intent into verifiable requirements. Executable specifications give code-generating agents a structured target and provide an independent check on their output. Agents can now draft those specifications from raw requirements, but closing the loop reliably still requires human validation of intent before code generation begins.
Why natural language alone is not enough for AI agents to generate reliable code
Shuzhao Feng and colleagues identify a decline in output quality as LLM generation scales from individual functions to repository-level systems. Their diagnosis concerns the input as much as the model. Natural language requirements can be read in different ways and provide no executable artifact to check the implementation against. An agent can therefore produce plausible code without establishing that it implements the intended behavior.
Additional prose may clarify individual details, but it can also compound ambiguity without creating a deterministic acceptance test. The verification gap follows from the input gap. When a requirement admits several interpretations, a reviewer cannot establish conformance merely by finding the generated code coherent.
What Gherkin is and why its structure is suited to machine consumption
Gherkin puts the intended behavior into a short, structured form. Its Given/When/Then syntax separates preconditions, actions, and expected outcomes so that humans and machines can read the same requirement. For agentic development, it serves primarily as a precision artifact. A scenario states the conditions under which a behavior must hold. Once connected to executable automation, it also supplies a pass/fail test of that behavior.
A declarative scenario describes submitting credentials and being redirected to the dashboard, while an imperative version specifies clicking the button with ID #submit-btn. The former names behavior, allowing the specification to survive implementation changes, whereas the latter ties it to a detail that can change without altering the requirement. This separation gives a code-generating agent freedom over implementation without giving it freedom to redefine the outcome.
The same artifact can be used as acceptance criteria, as living documentation, and as input for automated tests. Those roles reinforce one another because the requirement used to guide generation is also used to check the result. Static prose lacks that connection to execution. A well-written Gherkin scenario narrows interpretation by making the starting conditions and expected result explicit. Its value, however, depends on the precision of those statements.
Why AI-on-AI review without an external spec is circular, not additive
Christo Zietsman’s March 2026 paper argues that AI review becomes structurally circular when an executable specification is absent. The generating agent produces code, and the reviewing agent evaluates that code without ground truth against which to compare it. Both reason from the same artifact. The reviewer may identify internal defects, but it cannot establish fidelity to intent that was never expressed precisely.
A model that generates code and one that reviews it share architecture, training corpus, and reward signal when they come from the same family, so they can have correlated failures. Combining estimators helps when their errors are independent. Vallecillos-Ruiz, Hort, and Moonen’s 2025 study identified a “popularity trap” in which models converge on syntactically plausible but semantically wrong answers. Consensus selection can then amplify the shared error while filtering out minority correct solutions.
Zhendong Mi and colleagues’ work on coopetitive multi-agent prompting for Verilog generation provides a related example. Zietsman describes erroneous outputs being accepted downstream because agents shared the same training distribution, while single-agent self-review repeated original errors. Zietsman presents his broader specification-first argument as hypotheses supported by directional evidence. The mechanism nevertheless exposes a specific weakness in pipelines that treat model agreement as proof of correctness.
A well-written prompt can reduce ambiguity, but it cannot serve the same verification function as an executable scenario. The distinction is not length or writing quality. A prompt cannot be executed against the output to produce the behavioral verdict that Gherkin automation provides. AI review remains useful, but it needs an external reference established before implementation and independent of the coding agent’s interpretation. Where another agent drafts that reference, review against stakeholder intent is what prevents the same circularity from moving upstream.
How structured spec-driven engineering uses Gherkin as the bridge between requirements and repository-level code
Structured spec-driven engineering, or SSDE, places a structured specification between requirements and generated code. The specification performs two jobs at once. It constrains what the LLM should generate and supplies a test of the output’s conformance.
Zietsman frames this in Cynefin terms as a transition from the complex domain to the complicated domain, with executable specifications replacing enabling constraints with governing constraints. The practical change is a deterministic test of conformance. Feng and colleagues investigated the feasibility of this approach by generating Model-View-Controller business logic for three software systems using five LLMs. Their pilot addresses repository-level generation, where natural-language-only approaches degrade. It establishes feasibility rather than a guarantee of reliability across arbitrary repositories.
Feng and colleagues report an “impressive out-of-the-box ability in inferring software system properties through these specifications.” That ability gives the architecture its generative side. Requirements become Gherkin, which guides implementation and runs to check conformance before AI review looks for structural and architectural defects that the scenarios cannot catch. The remaining dependency is the production of the specification itself. Feng and colleagues acknowledge that “using LLMs to automatically produce structured specifications remains largely impractical” as of their study, leaving the loop open if specification authoring remains a human burden.
What it takes for an AI agent to generate usable Gherkin from raw requirements
Hassani, Sabetzadeh & Amyot’s 2026 study supports the practical value of LLM-assisted Gherkin generation. It found that 91.7% of ratings on the time savings criterion fell in the top two categories. That result concerns authoring effort. How good the output is still depends on how the requirements are written and whether the generated scenarios stay declarative.
The research describes generation in three phases. Requirement parsing extracts actors, actions, preconditions, and expected outcomes from unstructured material such as user stories or JIRA tickets. In scenario construction, those elements are then put into Given/When/Then syntax using patterns learned during training. In variation generation, the initial scenario is then expanded to cover positive paths, negative paths, and boundary conditions. This final phase offers the greatest coverage value over manual authoring, but its usefulness depends on selecting variations that reflect the actual domain.
Syntax alone is an insufficient quality bar. Generators trained on large BDD corpora can produce valid Gherkin while defaulting to imperative phrasing when the source requirements emphasize implementation details. More subtly, their scenarios may reflect common training examples rather than the boundary conditions of the system being built. Generic breadth can conceal domain-specific omissions. A usable specification must be declarative enough to preserve intent and precise enough that a code-generating agent cannot satisfy it by accident.
People therefore need to review the scenarios before the implementation is generated. The reviewer checks whether the scenarios express the intended behavior, cover relevant boundaries, and avoid binding acceptance to incidental implementation choices. This is a different task from writing every scenario. AI supplies the draft and its variations, while human attention validates the interpretation against the requirement.
What the closed loop looks like in an agentic pipeline from spec generation through merge
The operational loop begins when an agent turns a user story, ticket, or natural language description into a Gherkin feature file. Git stores that file as a versioned artifact. Once reviewed against intent, the specification becomes structured input for a second agent, or for the same agent in a new context window, to generate implementation code. This is the SSDE pattern applied to the handoff between agents. The approved feature file governs generation.
CI then executes the scenarios against the implementation. CI produces a deterministic pass/fail record for the specified behaviors. AI review follows with a narrower remit. It checks architectural decisions, security posture, and assumptions in cross-service contracts that the executable scenarios do not cover. The merge queue consequently receives a PR with a verification record attached, rather than relying solely on an AI reviewer’s judgment.
Versioning the specification makes behavioral changes visible across iterations. It also separates two distinct forms of drift. Code that diverges from the specification can produce a failing scenario, while a specification that diverges from stakeholder intent may still yield passing tests. GitOps makes the spec the source of truth for generation and verification, but does not make an inaccurate spec correct. Review of specification changes remains necessary to prevent the pipeline from faithfully implementing the wrong behavior.
Agent-speed throughput places pressure on the final handoff. Agents open PRs, revise them, and push follow-up commits faster than queues tuned for human-paced development were designed to handle. At scale, the loop depends on merge infrastructure that can manage this pressure without human intervention on every entry. An agentic merge queue must distinguish genuine spec-driven regressions from flaky infrastructure failures and triage CI results accordingly. Otherwise, deterministic verification improves the evidence for a merge without resolving the operational bottleneck around it.
What engineering teams need to do to put this architecture into practice
Before assigning implementation work to a coding agent, teams should have an agent or a human produce a Gherkin feature file from the requirement. Code generation should wait until that file has been reviewed for declarative completeness and domain accuracy. Teams can migrate incrementally by making specification generation the first stage of agentic coding tasks.
Teams should version feature files in the same repository as the code and use their execution in CI as a merge gate. That makes the behavioral contract visible in pull requests. A PR that changes behavior without a corresponding specification change is a signal to examine before merging. AI review should then look for defects that the scenarios do not catch, including those in architectural decisions, security assumptions, and cross-service contracts. A passing suite establishes conformance within the scope of the behaviors it specifies.
Teams working at agent-speed throughput should use queue automation that can handle CI triage, flake classification, and queue management without a person stepping in on every entry. The unresolved research challenge belongs at the specification stage, where AI-generated Gherkin should remain a high-quality draft subject to human judgment. Reliable automation begins when intent has been approved, and its authority extends only as far as the executable contract defines.